
Selected model is at capacity. Please try a different model.
“Selected model is at capacity. Please try a different model.”
I find this message increasingly difficult to accept.
It appears precisely when I have decided that a task deserves a particular level of intelligence. I have chosen the model, supplied the context, and prepared the work. Then the service asks me to make another choice because the capacity to deliver that intelligence is unavailable.
For an occasional experiment, that is an inconvenience. When AI becomes part of how a team develops software, makes decisions, or serves customers, it becomes a business problem.
How dependable does AI need to become before enterprises can depend on it?
The decimal places matter
The two status-page screenshots below caught my attention. The ChatGPT screenshot reports 99.52% uptime. The claude.ai screenshot reports 99.53% over the previous 90 days.

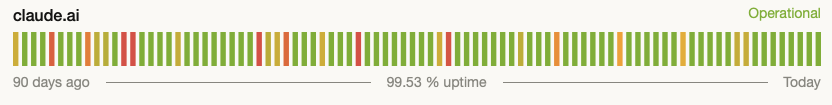
There is an important qualification. These screenshots concern ChatGPT and claude.ai. Enterprise API contracts have their own scope and commitments. OpenAI’s status page also explains that its availability metrics aggregate tiers, models, and error types, and that individual customers’ experience can vary. A coloured day can represent a partial incident or degraded performance; it does not mean everybody was unable to work for 24 hours. The Claude status page separately tracks its web application, API, and coding service.
Even with those qualifications, the percentages deserve attention. For business-critical AI workflows, I would start with an availability target of 99.95%. Some applications will need more. Others can tolerate delays. The requirement should follow the consequences of failure.
99.50% and 99.95% may look almost identical in a presentation. Express them as time and the difference becomes much harder to dismiss.
| Availability | Downtime per month | Downtime per year |
|---|---|---|
| 99.50% | 3 hours 36 minutes | 43 hours 48 minutes |
| 99.95% | 21 minutes 36 seconds | About 4 hours 23 minutes |
The difference is only 0.45 percentage points. It represents ten times as much downtime at the lower level of availability.
And the business impact depends on when those minutes arrive. An interruption during an overnight background job is different from one during a customer escalation or a software release. The percentage is a starting point. The interrupted work is what the enterprise experiences.
“Try a different model” changes the work
There is something particularly uncomfortable about the suggested remedy.
If I selected a model because I trust it with a difficult programming task, asking me to use a less capable alternative asks me to reconsider the quality of the work I am prepared to accept.
Of course, another model is not automatically worse. A smaller model may be excellent for a well-defined task. A team that has evaluated several models can switch between them with confidence.
But that is a decision supported by evidence. A capacity warning supplies no evidence that the alternative is suitable for the task in front of me.
The relevant question is whether the fallback can meet the same requirements: understand the existing code, preserve its contracts, handle edge cases, and produce a change that survives review. Keeping the conversation moving tells us very little about those requirements.
The interruption ends. The code remains.
This matters because generated code can outlive the circumstances that produced it.
The capacity problem may disappear this afternoon. The code written during it may stay in production for years.
Imagine a developer switching models halfway through a feature. The replacement produces a patch that appears reasonable and passes the available tests. It is merged. Months later, a maintenance problem exposes an assumption that nobody examined closely enough.
That scenario can happen with any model, including the most capable one. The additional concern is whether the team knows that the conditions under which the work was generated changed.
Can we trace which model and version contributed to a change? Do we know when a fallback occurred? Can we connect that information to the pull request, the tests, and the human review? Was the fallback approved for that type of work?
Recording the model does not prove that the code is correct. It gives the team context for investigating problems and deciding where additional review is warranted.
Availability should include access to the level of capability the workflow requires. A service can continue returning answers while the team loses confidence that those answers meet its standards.
More capacity has a physical cost
The immediate response is obvious: build more capacity.
Some expansion is necessary. But servers need electricity. They produce heat that must be managed. Their carbon impact depends on the electricity supply, as well as manufacturing and the infrastructure around them.
The International Energy Agency’s 2025 Energy and AI report estimated that data centres consumed about 415 terawatt-hours of electricity in 2024. Its base case projected around 945 terawatt-hours in 2030. Those figures cover all data centres, with AI an important driver of the projected growth.
Simply adding machines every time demand rises creates an increasingly demanding relationship between intelligence and energy. Enterprises need reliable service, while the energy system must accommodate the physical requirements behind it.
That makes efficiency central to the solution. In the IEA’s high-efficiency scenario, stronger improvements in hardware and AI models reduce projected data-centre electricity demand in 2035 by 20% relative to its base case. That is a scenario, rather than a guaranteed outcome, but it shows why the engineering choices matter.
A brain runs on roughly 20 watts
The human brain offers a remarkable reference point.
Its metabolic power consumption is commonly estimated at roughly 20 watts. A 2021 study by William Levy and Victoria Calvert, published in the Proceedings of the National Academy of Sciences, discusses that familiar estimate and uses about 17 watts of glucose-derived potential energy in its own audit.
The brain is an expensive organ by biological standards: roughly 2% of adult body mass accounts for about 20% of resting energy expenditure. That is an unusually large share compared with many other species. Yet comparative research by Suzana Herculano-Houzel found broadly similar average energy use per neuron across the rodents and primates studied, including humans.
This does not give us a simple efficiency ratio between a brain and an AI system. A data centre serves many users, the tasks differ, and both systems depend on supporting infrastructure. “Intelligence per watt” needs a definition of the intelligence being measured.
Still, the biological example is striking. Learning, perception, reasoning, and adaptation can coexist within a modest power budget. It suggests how much room there may be to improve the way we engineer artificial intelligence.
Dependable intelligence, delivered efficiently
For enterprise AI, I would measure efficiency in terms of energy per successfully completed, validated task. That includes failed attempts, retries, and the rework required to obtain an acceptable result.
A smaller model that reliably completes the task can be an excellent choice. A larger model may justify its consumption if it solves a problem that would otherwise require repeated attempts and extensive correction. The useful comparison starts with the work that actually gets done.
Better efficiency can also help relieve capacity pressure: doing useful work with fewer resources creates room to serve more demand. Reliability still requires sound operations, software, and infrastructure; efficiency alone will not prevent every outage.
But the direction seems clear. AI needs to become more capable, more dependable, and less energy hungry. Enterprises should expect progress on all three.
Every time I read “Please try a different model,” I am reminded that our dependence on AI is growing faster than our confidence in its delivery.
The industry’s challenge is to make the intelligence we choose available when we need it, at an energy cost we can sustain.


